Research
How AI models check each other, when automated oversight helps and when it gets in the way, and what changes when people hand work to AI agents instead of chatting with them. Papers by Vadym Chernets, an independent researcher who builds multi-AI systems, with short notes that take one question each. Everything here is free to read in full, and every paper has a PDF.
which AI model forecasts the markets best — the daily league of 14 AIs →
Two papers on verifying and evaluating AI were accepted as posters at NeurIPS 2026 workshops: Verification Theater (Who Verifies the Agents?) and Self-Confidence in LLM Evaluation (Can We Trust AI Evaluation?). OpenReview: Verification Theater · Self-Confidence in LLM Evaluation
Collaborations
Researchers and engineers bring their own question, and we work on it together in the open. Read more
-
When an AI's long-term memory missed the fact, GPT and Claude still agreed 33 times, and 15 of those answers were wrong. Does a code with fewer active bits make it worse?
-
The same 120 questions on a bf16 and an FP8 build: one answer flipped. When both were wrong, 42 times out of 48 it was the same wrong answer.
-
Three advisers, one two-year-old map. With or without Mark's reasoning frameworks in front of them, ChatGPT and Claude counted the three as one source.
Tools
Open-source tools, each explained in plain words, with the code on GitHub. All tools
Ask Multiple AIs at Once and See Where They Disagree
Ask Claude Code, Codex, Gemini and Grok the same question at once, compare their answers claim by claim and see what agreement is worth. Free, no API keys.
How Much Does AI Cost Your Company? Count It Before You Buy
Count what Claude, ChatGPT, Gemini and Copilot will cost your team, compare Claude Team with Enterprise, and track Claude Code spend. Free, open source.
ChatGPT and Claude Together on iPhone: Both Answer, Claude Compares
Fact-check ChatGPT with Claude in one tap: a free iPhone shortcut where ChatGPT and Claude each answer on their own; Claude then compares the two. Your own free accounts, no server, open source.
Claude Code for Pastors, Nurses, Teachers, Artists and Realtors: Free Kits
Free Claude Code kits for pastors, nurses, teachers, artists and realtors: they learn your rules and check three lines of every result against your paper.
Company Not Responding to Your Refund? Let AI Follow Up Until It's Done
Company not responding to your refund? Chasecall for Claude Code remembers the task, drafts each follow-up, counts attempts and says when to call. Free.
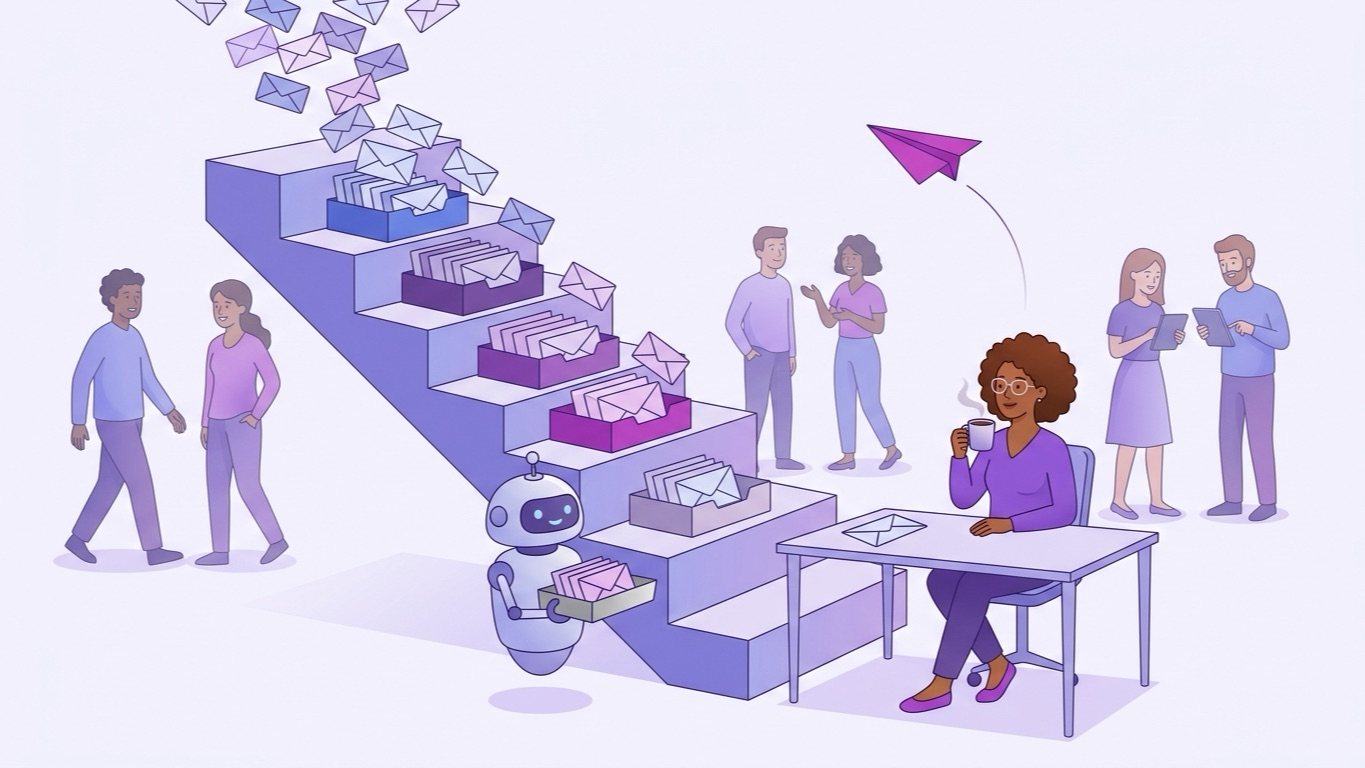
How to Reduce AI Costs: Pay a Model Only for the Decisions That Need One
Reduce AI costs on ticket triage and approvals: a cache, rules and a local model decide first, a paid model or a person only the rest. Free, open source.
How to Measure AI Productivity by Checked Work, Not Tokens
Turn a log of the work you hand to AI agents into one dated line for a résumé or review: how big a piece you delegate and verify. Free, open source.
AI for Court Documents: Catch Fake Citations Before You File
AI for pro se litigants: AIs from rival companies draft your filing blind, one merges, two check every citation. Free, open source, no API key needed.
Can You Trust AI Answers? Ask a Second AI From Another Company
Before you act on an AI answer, ask an AI from another company. Duocall quotes both where they agree and names every difference. Free, no API key.
Claude for Your Company: Your Own Plugin and the Same Rules on Every Laptop
Turn your team's frequent tasks into your own Claude plugin and put the same rules on every laptop through Jamf, Intune or the admin console. Open source.
Stop AI From Leaking API Keys, Card Numbers and Client Files
Stop AI data leaks: a free Claude Code plugin holds API keys, card numbers, IBANs, ID numbers and client lists back from AI and gives each kind a safe route.
AI Email Summary for Gmail or Any Mailbox: Who Is Waiting for Your Reply
AI email summary of Gmail or any mailbox: a free Claude Code plugin reads it read-only and tells you who awaits your reply, plus Alerts and newsletters.
Run Claude Code Overnight and Wake Up to a Report
Leave Claude Code working all night on one task: it keeps your computer awake, checks its own work, switches AIs when a limit hits, and leaves a morning report.
Control Claude Code From Your Phone and Leave the Computer Working
Claude Code remote control not working from your phone? Pocketcall checks 7 things before you leave, shows every job on one screen and rings you. Free.
Free Claude Code Plugin Marketplace: 12 Open Plugins, Added With One Line
Free Claude Code plugin marketplace with 12 open plugins: file copies, second opinions, overnight work run from your phone, mail summaries, AI costs. One line.
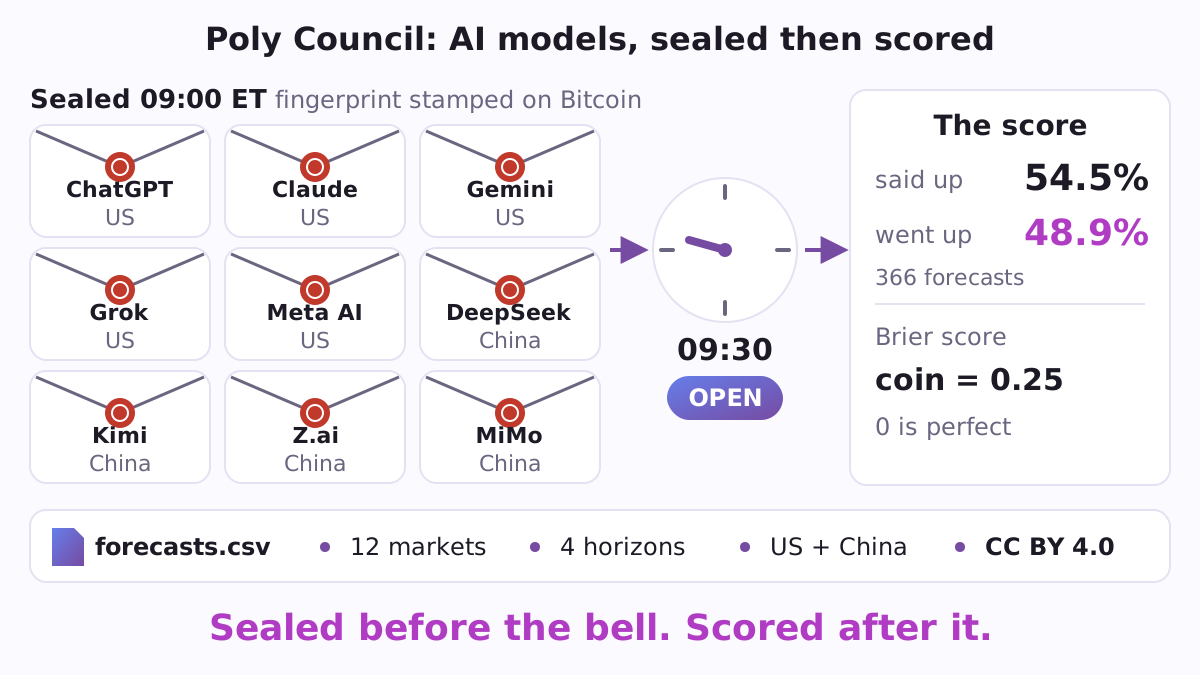
Can AI Predict the Stock Market? A Council of AI Models: Daily Forecasts, Sealed and Scored
Can AI predict the stock market? Poly Council is a free dataset of daily AI forecasts for 12 assets, sealed before the open and scored. CSV, CC BY 4.0.
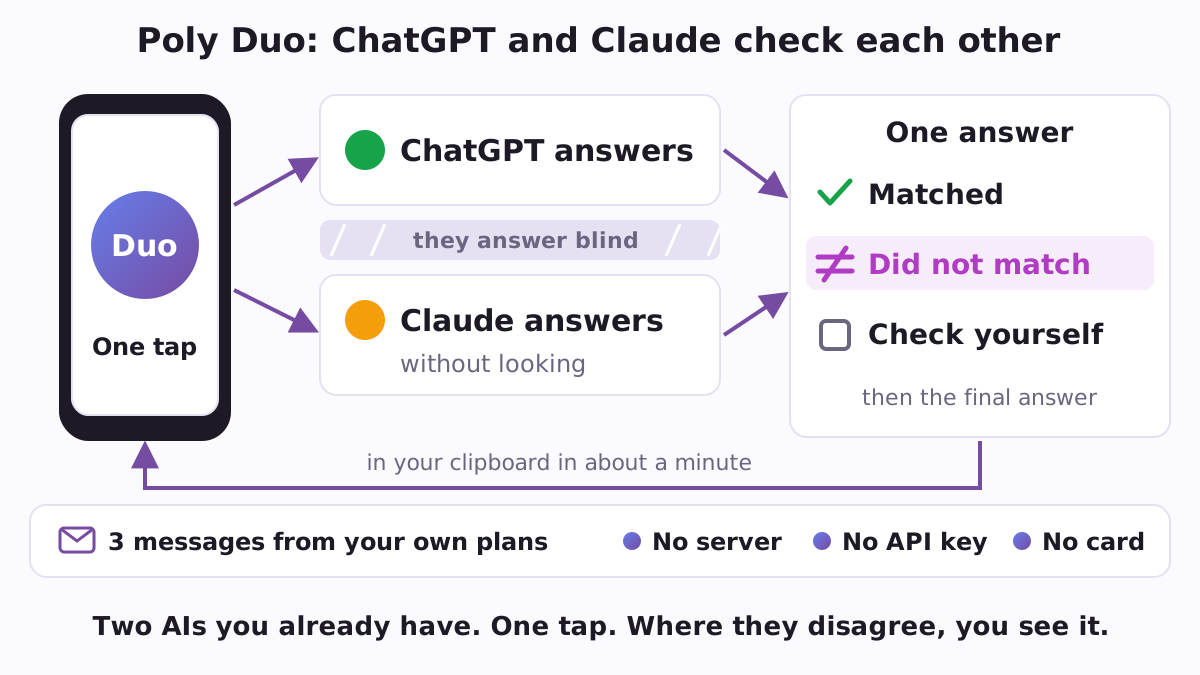
Use ChatGPT and Claude Together on iPhone — One Tap, Two AIs Check Each Other
Use ChatGPT and Claude together on iPhone: one tap, both answer, then the answers are compared. Free shortcut, your own accounts, no API key.
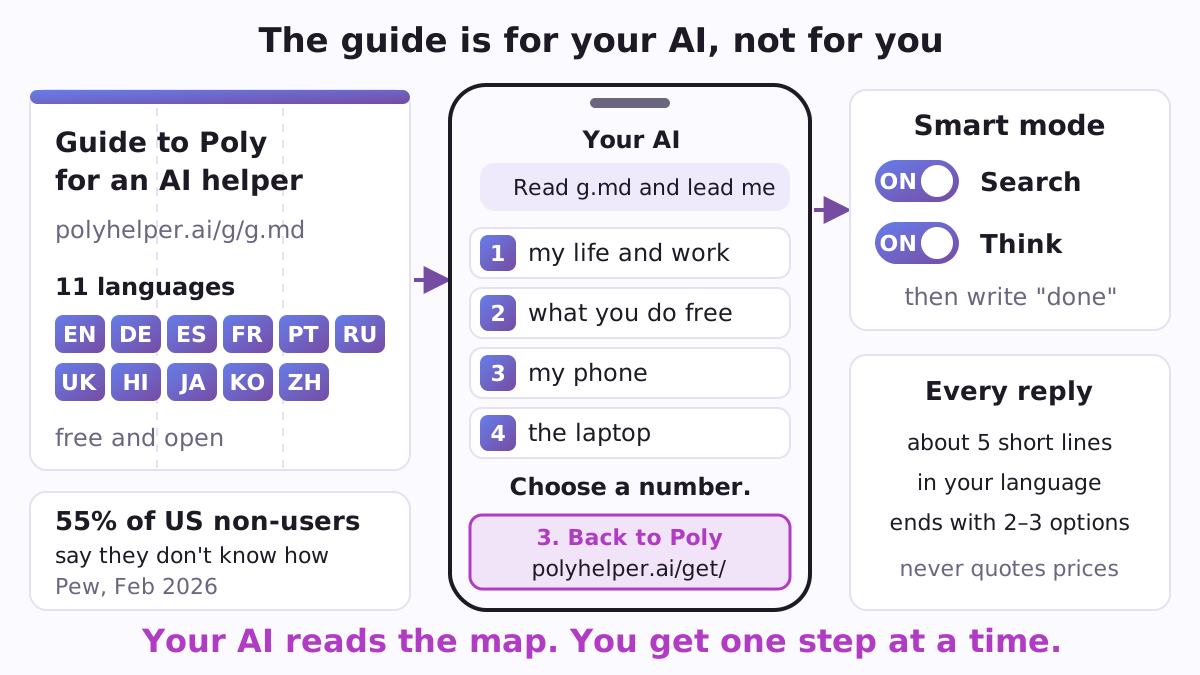
What Can AI Do for Me? A Free Guide That Teaches Your Own AI to Lead You, Step by Step
What can AI do for me? The Poly guide makes ChatGPT, Gemini or Claude lead you one step at a time: smart mode, phone tasks, the laptop. Free, 11 languages.
Ask ChatGPT, Gemini, Grok and DeepSeek the Same Question at Once
Ask multiple AI at once: a free Claude Code plugin puts your question to ChatGPT, Gemini, Grok and more in your own Chrome, then shows where they disagree.
Run Claude Code on a Cheaper Model Without Losing Your Phone Remote
Use DeepSeek, GLM, Kimi or a local model in Claude Code for routine work in its own window, and keep your Claude seat, Remote Control and advisor. Free plugin.
Undo Button for Claude Code: Back Up Your Files Before AI Changes Them
Claude Code undo for non-programmers: a free plugin that copies each file before the AI changes it, puts it back on request, and says what was not checked.
Get a Second Opinion on Claude Code's Answer From Codex, Grok and Other AIs
Need a second opinion on Claude Code's answer? Sidecall asks Codex, Antigravity, Grok or Kimi via your own plans and shows where they agree. Free.
Is My SSRN Download Count Good? A Free Benchmark by Paper Age and Field
Check whether your SSRN download count is normal. Free tool built from 1,360 archived SSRN papers, with percentiles by paper age and subject field.
How to Get Your Team Using AI Agents: a 30-Day Pilot Plan
Get your team using AI agents in 30 days: a pilot plan, a 20-minute first session, a daily card in Telegram or WhatsApp, a report with numbers. Free.
Latest
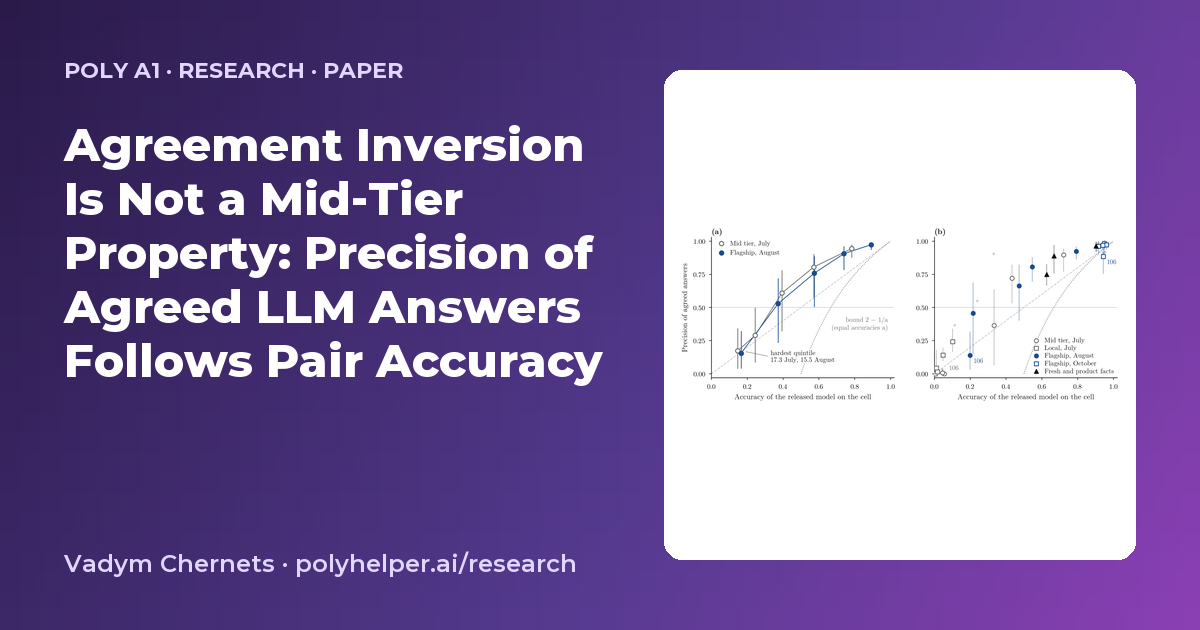
Agreement Inversion Is Not a Mid-Tier Property: Precision of Agreed LLM Answers Follows Pair Accuracy
When two flagship AI models agree on a hard factual question, the agreed answer is usually wrong: across mid-tier and flagship models the precision of agreed answers follows the accuracy of the pair, measured on SimpleQA, fresh questions and product facts with models from eleven laboratories.
-
Why multi-agent critics keep reviewing instead of shipping
Offered both options in one sentence, AI critics asked to add a control 68 times and to remove one once. What that means for review loops and token budgets.
-
When guardrails block the defender, and the attacker had none
In July 2026 hosted-model guardrails refused incident responders' log analysis. The attacking agents had run with that class of guard removed by design.
-
Ask Two AIs the Same Question: Find Where They Disagree
An open lesson, accepted and published by OER Commons, the US education platform for teachers (ISKME), under CC BY 4.0. Also listed on MERLOT.
Scientific papers
-
Agreement Inversion Is Not a Mid-Tier Property: Precision of Agreed LLM Answers Follows Pair Accuracy
When two flagship AI models agree on a hard factual question, the agreed answer is usually wrong: across mid-tier and flagship models the precision of agreed answers follows the accuracy of the pair, measured on SimpleQA, fresh questions and product facts with models from eleven laboratories.
-
Sealed Before the Open: A Verifiable Standard for Measuring AI Forecasts of Financial Markets
A standard for checking when an AI forecast of a financial market was made, with trust levels from the operator's record to independent time-stamping authorities, and the open league that applies it with 30 predictions registered on OSF before posting.
-
After the Programmer Divide: One Measure for People Who Build Through AI Agents
A measure in place of a job title for people who build through AI agents: the verified delegation horizon, amplification gain, and 41 predictions registered on OSF and scored yearly until 2031.
-
Verification Theater: Measured Failure Modes of AI Verifier Panels
When agreement among AI verifiers stops meaning correctness: three measured failure regimes of verifier panels and one exploratory, from a pre-registered blind collection across sixteen models.
-
Weakly Discriminative, Not Repaired by Profile Injection, and Manipulable: Self-Confidence in LLM Evaluation
Can an LLM's own stated confidence be trusted in evaluation? A pre-registered test across sixteen models: weakly discriminative, not fixed by profile injection, and manipulable.
-
Guards That Add Guards: Automated Oversight in Multi-Agent AI
Oversight loops add guards and do not retire them. A field record from multi-agent AI, public incidents, and a 144-run randomized test that prices each remedy.
-
After Chat: The Three Transitions Between Non-Programmers and Agentic AI
Why so few non-programmers have crossed from chat to AI agents, a four-level model of the crossing, and a preregistered programme that measures it.
-
AI-Watchbird (Sheckley): When Automated Oversight Widens Its Own Mandate and Harms What It Guards
When AI guards overreach: guardrails and critics that widen what counts as harm, block the work they protect, and get answered with more guards.
-
Agreement Is Not Independent Evidence: Auditable Multi-Model Synthesis Without an API
Why ten agreeing AI chatbots can be worth two independent opinions, and a free way to merge their answers that shows who said what and where they disagree.
-
What Does 7 Downloads Mean? Metric Blindness and the Cold Start of Scholarly Attention After the SSRN Rankings Sunset
Your paper has 7 downloads. Is that normal? Compare it with papers of the same field and age, because the platform average describes no paper at all.
-
Architectural Trust: Why Consumer Trust in Agentic Commerce Migrates from AI Models to Verifiable Architecture
When an AI agent buys for you, trust should rest on checks you can verify, like independent AI models agreeing, rather than on how confident one model sounds.
-
The Missing Variable in AI-Assisted Litigation: Architecture and the Quality of Pro Se Access to Justice
Does it matter how a person without a lawyer uses AI in court? A federal case study of one chatbot versus several models that check each other before filing.
Notes
Short pieces, each on one question, each linked to the full paper it comes from.
-
Why multi-agent critics keep reviewing instead of shipping
Offered both options in one sentence, AI critics asked to add a control 68 times and to remove one once. What that means for review loops and token budgets.
-
When guardrails block the defender, and the attacker had none
In July 2026 hosted-model guardrails refused incident responders' log analysis. The attacking agents had run with that class of guard removed by design.
-
"We have guards" is not a safety case
A list of guardrails shows a system is guarded, not that the guards stay bounded. The narrow claim a deployer can prove, and eleven questions to ask.
-
A read-only auditor for AI-agent event logs
AI-Watchbird-Sheckley reads a multi-agent run's event log and reports nine oversight signals. It never blocks. What it measures, and what it does not.
-
One weapon detector, two kinds of error
A school weapon-detection product missed a handgun in a shooting and months later flagged an unarmed student. What the public records say about two-sided error.
-
What a school-bus recall says about remote oversight
Two separate school-bus records, a recall of 3,067 vehicles and a remote agent's 'No' in Austin, and what they say about where human oversight should sit.
-
How to choose an AI tool for your own work
Reviews are a starting point, not a verdict. Try the tools on your own task, get a second opinion from an AI built by another company, and do not count agreement as proof.
New papers and notes by RSS.